Which local model should you actually run?
The model list changes monthly, so this page does not rank them. What fits in 8 GB or 16 GB of memory, a prompt that picks for your machine, and a one-week test.

By Nick
On this page
- Fifteen minutes, then a week of use
- Free
- Intermediate
Before you start
Learn
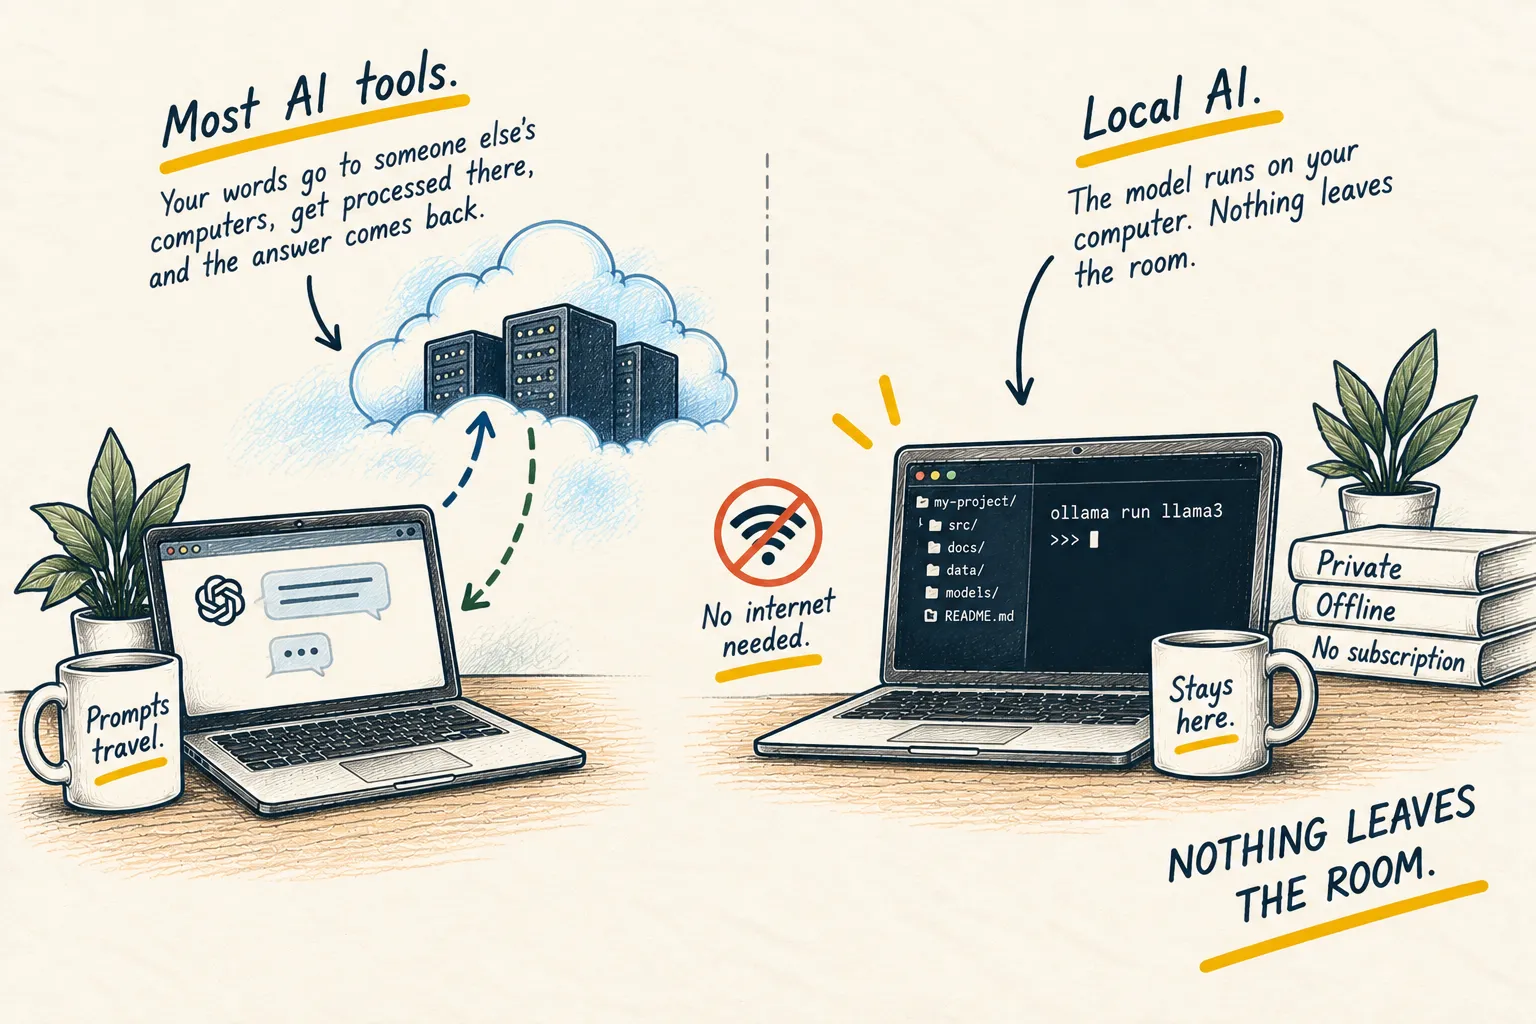
What is local AI?
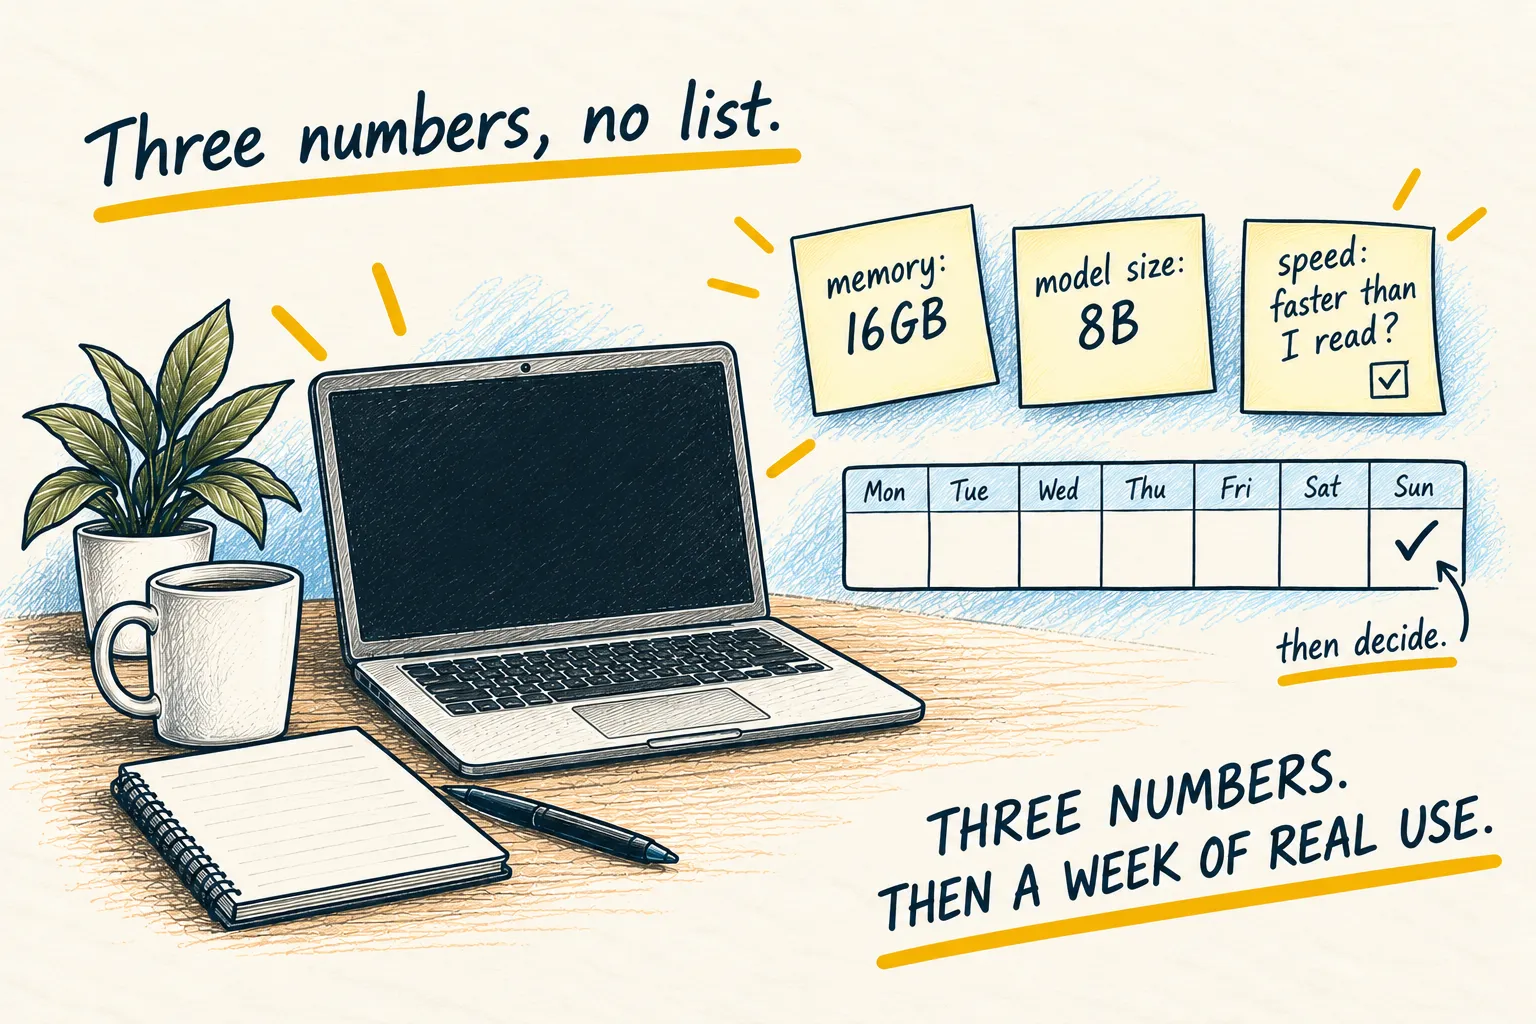
1. The three numbers
Memory. The limit. Under 8GB, small models only and it will be slow. 8 to 16GB, the small-to-medium ones. 16GB and up, you have choices. Apple Silicon Macs punch above their figure because the memory is shared with the graphics chip.
Model size. The B number: billions of parameters. Bigger is cleverer and slower. Rule of thumb: a model needs a bit more memory than its size in gigabytes.
Speed. If a reply arrives slower than you read, you will stop using it. That is the test that overrides the other two.
2. Let it pick for your exact machine
Paste this into an agent on your own computer. It reads the machine and the current model list, which is why this page has no names in it.
Look at this machine's memory and graphics chip, check what local model runner is
installed, and recommend one model for everyday text work: rewriting, summarising,
drafting, answering questions about my files. Pick from what is currently available and
well regarded, not from memory. Tell me its size, how much disk it needs, and why it fits
this machine. Then download it, run one short test question, and tell me how long the
reply took. Do not download a second model until I have used this one for a week.
3. Use it for a week on real work
Not trivia; small models are worst at trivia. The work you would actually use it for. After a week, you know. Too slow: one size down. Too dim: one size up. Fine: stop shopping.
Agent on a 16GB MacBook, plus the prompt above
This machine has 16GB of memory and an Apple chip, and Ollama is installed.
I recommend an 8B general-purpose model. It needs about 5GB of disk and leaves enough memory free for your other apps.
I downloaded it and asked it to summarise a paragraph in one line. The reply took 4 seconds. I have not downloaded anything else.
If the test reply took longer than you read, say so and ask for a smaller model.
Before you trust it with anything sensitive, read local is not private, and keep a hosted model for the hard problems.